What happens when an enterprise data agent asks you: “What is our churn this quarter?” The AI agent has access to the warehouse, the tables, and the query engine. It carries out the necessary calculations. However, the answer it provides turns out to be inaccurate. Why?
It’s not because the model is inadequate. It’s because it didn’t know which definition of the term 'churn' the business had in mind, which table was out of date, or which join resulted in customers being counted twice. When you apply this situation to all the questions your enterprise directs at AI, you begin to understand why so many agent projects come to a halt at the demo stage.
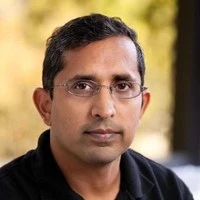
In this episode of the Don't Panic, It's Just Data podcast, host Shubhangi Dua, Podcast Producer and B2B journalist at EM360Tech, sits down with Suresh Srinivas, the CEO and Co-Founder of Collate and also a Co-Founder of the open-source project OpenMetadata. They talk about the context layer and the reasons why AI agents fail when it comes to enterprise data, even though the underlying models are continually getting better. He explains why the solution must be an open context layer rather than a proprietary one.
Does Your AI Understand the Business Context?
Alluding to a finding by McKinsey that shows almost two-thirds of companies are experimenting with AI agents, although less than 10 per cent have managed to scale them to real value, 80 per cent of the companies point to data limitations as the reason. Dua asked Srinivas why the data continues to hold back AI evolution.
The OpenMetadata co-founder responds, “I don’t think the data is holding AI back.” He explains that we don’t have the right foundation to enable AI with the data. “AI doesn't know what data exists in enterprises today. It doesn't understand the meaning of the data. It doesn't understand the business context.”
Because large language models (LLMs) are trained on generic data, they don’tcomprehend the enterprise at all. When the models are generic, the business is harder to understand, and this is the challenge the industry is still grappling with.
This is where Collate comes in. Srinivas tells Dua about research carried out by Collate using their own evaluation framework, Spider 2.0, a benchmark which assesses the accuracy of AI over enterprise data for a variety of models. The result showed that the more recent and larger models made no difference to accuracy; the best model still achieved only 59 per cent, that is to say, more than 40 per cent of its answers were incorrect.
Introducing a context layer directly affected the results. Using the same benchmark and the same models, Collate's context platform increased accuracy from 59 per cent to 94 per cent, which meant that the number of incorrect answers was reduced by 86 per cent.
When Data Agents Meet Metadata
How OpenAI’s Kepler uses governed schemas, lineage, and query history to turn days of manual data work into 90‑second self-service answers.

Further to that, token consumption was reduced by 75 per cent, and the number of database queries the AI had to make in order to answer a single question decreased from 190 to 27 (an 86 per cent reduction in compute). Srinivas regards all three of these outcomes as being caused by the same solution: an agent that knows what data is available and what it means does not need to guess, re-query, or waste tokens in order to find out.
Also Read: OpenAI's self-service AI data agent, built on OpenMetadata
What OpenAI's internal data agent shows about scale
Srinivas cites a use case to Dua to explain how the solution can be deployed at scale. He talks about OpenAI's own internal data agent, Kepler, which is used by more than 3,500 people and carries out reasoning across about 70,000 datasets and over 600 petabytes of data, as proof that the issue is not particular to Collate's customers.
OpenAI developed a seven-layered context system based on OpenMetadata, and is one of its largest users as well as a major open source contributor. Srinivas maintains that even though there are seven layers, they all come down to three basic elements: the context of the data (what exists), the ontology and semantics (what it means, expressed in business terms such as "revenue" or "churn"), and memory (the corrections and feedback that the agent learns from).
Srinivas states that after OpenAI had invested in the context layer, query performance on Kepler decreased from 22 minutes to 90 seconds, representing a roughly 16-fold improvement, together with improvements in token efficiency.
Anthropic too has published its own research on the importance of context layers for data agents, which shows that there is convergence among the leading research labs, not merely a point made by Collate.
Unifying Semantics Across Data
Fragmented revenue and customer definitions across platforms erode AI reliability. See how a shared layer changes the economics.
Why the Context Layer Needs to be Open
“AI is going to transform how we do data in a big way, just like AI is transforming coding,” the CEO tells Dua. “Better models with your data don't make the AI better, but better context does.”
When Dua asked about who should be held accountable for stale data in the enterprise for AI use, Srinivas says the data teams own the context for the metadata and semantics are owned by domain experts who understand the business. “Memory becomes a responsibility of every data consumer, every interaction that you're doing with AI, from capturing the feedback, the corrections.”
“All these different roles need to come together to curate and continuously improve the context layer,” he added. However, it’s challenging to process it all manually. This is where Collate comes in. Srinivas tells Dua that Collate developed AI agents that help automate the feedback and corrections and continuously update and curate the context to aid enterprise users’ workflows.
Essentially, AI agents work in conjunction with people while continuously curating the context.
When asked about the risks involved in open-sourcing something so central to an AI strategy, Srinivas rephrased the question. What risk exists in incorporating your context into a proprietary solution? Since frontier models are becoming more commoditised, it is the context layer which determines accuracy.
Considering that it has become easier to swap models in and out, the context layer rather than the model has become the firm's true source of competitive advantage. If that layer is developed within a closed vendor system, the investment will be stranded should the vendor relationship change.
AI’s Hidden Semantic Risk
Fragmented metadata lets agents ship confident, wrong answers at scale; see the cost model for fixing it with a unified layer.
OpenMetadata is the solution, the Collate CEO tells Dua. He adds that OpenMetadata is the leading open-source model for the context layer and has more than 15,000 members in its community in addition to 4,000 production deployments. Srinivas explains what "open" means in three respects: in terms of open source (so that the context is not tied to a vendor's system), through the use of open standards such as RDF for representing semantics and ontologies, and via open vocabularies, meaning the use of existing standard definitions for concepts like "customer" or "churn" and thus eliminating the need for enterprises to redefine them from scratch.
Overall, larger models do not correct wrong answers when it comes to enterprise data; instead, an open and curated context layer does. To remain the enterprise’s asset rather than the vendor's, it must be located outside any single vendor's premises.
AI governance is another key aspect enterprises have to divert their focus on. Since the number of agents is increasing, very few enterprises can state which agents are in operation, what data those agents are coming into contact with, or whether that access is in line with the rules.
In response, Collate has launched an AI Governance Studio in order to provide organisations with a list of their AI agents, an assessment of the risk each one presents, and an audit trail showing what they access.
Key Takeaways
- McKinsey: fewer than 10 per cent of enterprises have scaled AI agents to value
- 80 per cent of enterprises cite data limitations as the scaling barrier
- On the Spider 2.0 benchmark, the top models achieved only 59 per cent accuracy when tested on enterprise data.
- Collate's context layer raised accuracy from 59 per cent to 94 per cent on the same benchmark
- That's an 86% reduction in wrong answers from context alone, not a bigger model
- Token spend fell 75 per cent once a context layer was added
- Database queries per question dropped from 190 to 27, an 86 per cent reduction in compute
- OpenAI's Kepler agent spans 70,000 datasets and 600+ petabytes, built on OpenMetadata
- OpenAI's query performance improved from 22 minutes to 90 seconds with context
- Context layer reduces to three primitives: data context, ontology/semantics, memory
- OpenMetadata has 15,000+ community members and 4,000 production deployments
- Collate curates context per persona rather than serving the full context to every agent
- Collate's AI Governance Studio audits what agents access and the risk they pose
Learn more at getcollate.io.
Collate is the agentic orchestration and automation platform for data, built on OpenMetadata, the open context layer for AI. More than 4,000 deployments, including Global 2000 enterprises and fast-growing startups, run on Collate's context, ontology, and memory to keep people and AI agents working from the same understanding of data. The result: trusted analytics, governed AI agents, and automated governance at enterprise scale. Learn more at getcollate.io.

Comments ( 0 )